A small thing we noticed while working on document automation:
Payment receipts are easy to read, but surprisingly difficult to process at scale.
A receipt can arrive as a screenshot, scanned image, or PDF. The information is visible, but someone still has to manually read it and move the important details into another system.
That might mean copying:
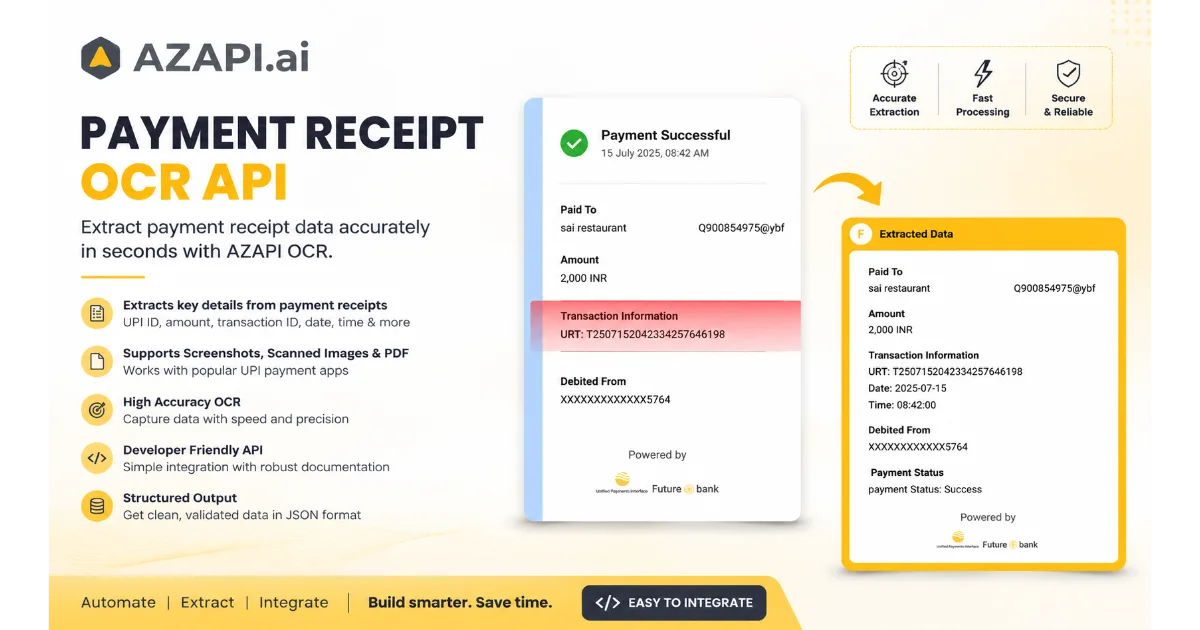
- Recipient or payee name
- UPI ID
- Amount and currency
- Reference or transaction ID
- UTR number
- Payment status
- Date and time
Doing this occasionally isn't a big deal. But when a business handles hundreds or thousands of receipts, those small manual steps start adding up.
This is one of the problems we’re working on with the AZAPI Payment Receipt OCR API.
The idea is simple: extract useful information from supported payment receipts and turn it into structured data that applications can actually use.
That data can then fit into workflows for payment reconciliation, accounting, financial records, expense processing, dashboards, and fintech applications.
What interests me most is that automation doesn't always need to replace an entire process.
Sometimes, removing one repetitive step is enough to make a workflow significantly better.